Istio Gateway API Inference Extension
This post analyzes how the Gateway API Inference Extension is implemented and operates in Istio. Istio supports the Gateway API Inference Extension starting from Version 1.27, and the analyzed Istio Version is 1.31 with Gateway API Inference Extension Version v1.6.
1. Istio Gateway API Inference Extension
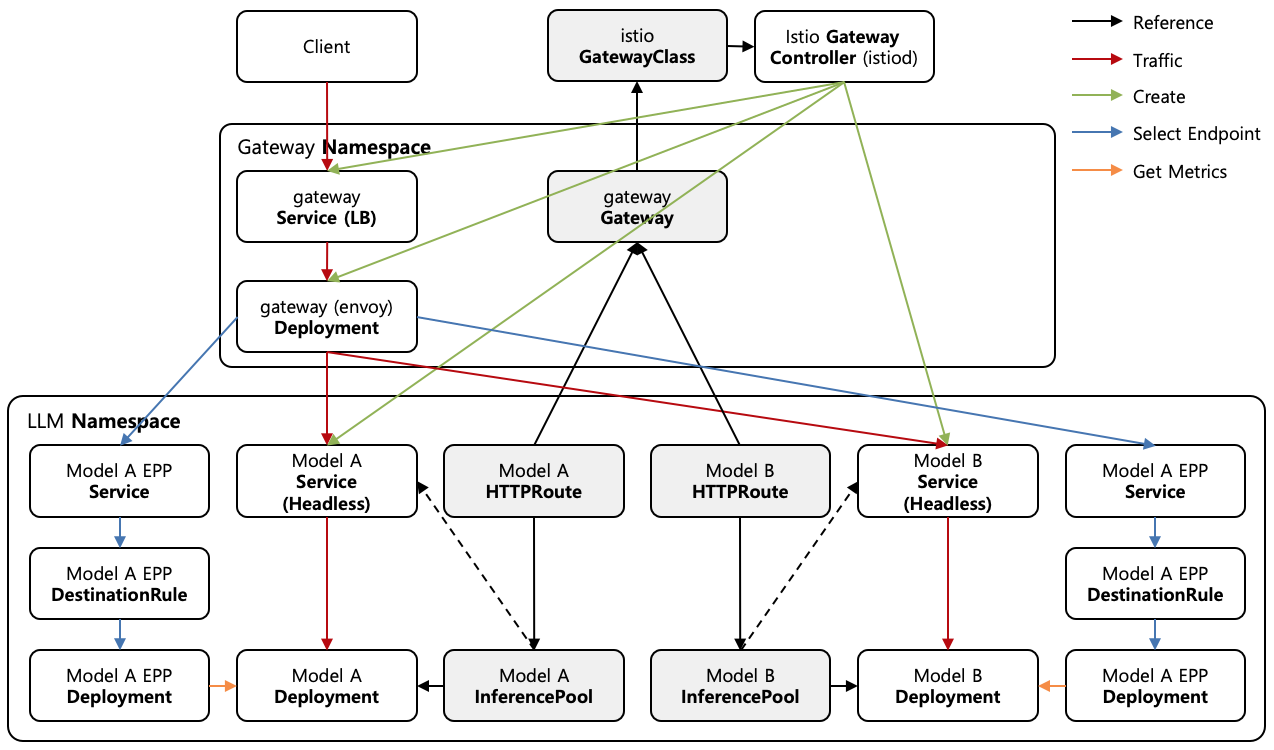
[Figure 1] Istio Inference Gateway Architecture
The Gateway API Inference Extension is an extension standard of the Gateway API for controlling Inference Traffic delivered to LLM Model Servers, and Istio serves as an implementation of the Gateway API Inference Extension just as it does for the Gateway API. The Controller role is handled by istiod without installing a separate Controller; istiod’s InferencePool Controller Watches Inference Resources such as InferencePools and InferenceObjectives, and when an HTTPRoute that references an InferencePool exists, it converts the InferencePool into the existing Service Model.
[Figure 1] shows the architecture of the Istio Inference Gateway. The configuration converted by the InferencePool Controller is gathered into the PushContext together with the Gateway API Resource, Istio CR, and Kubernetes Service configuration Watched by the Gateway API Controller, the crdclient, and the Service Registry respectively, and after the ConfigGenerator converts it into Envoy Listener and Route configuration, the DiscoveryServer delivers it to the Gateway’s Envoy via xDS.
Like the llm Namespace in [Figure 1], a single Model consists of the combination of a Model Server Deployment, an InferencePool that defines the set of Model Servers, an HTTPRoute that forwards Traffic to the InferencePool, and a dedicated EPP (Endpoint Picker) that selects the optimal Model Server, and the EPP that exists per Model collects only the Metrics of the Model Servers it is responsible for.
istiod creates not only the Gateway’s Envoy Deployment and Service but also a Shadow Service corresponding to the InferencePool, like the model-a Headless Service in [Figure 1]. The Shadow Service is a hidden Headless Service that istiod creates on behalf of the InferencePool, so that Istio can handle the new InferencePool concept in the same way as existing Services instead of processing it directly. Since the Shadow Service’s selector is set to the InferencePool’s selector, the Model Server Pods selected by the InferencePool are registered and managed as the Shadow Service’s Endpoints, just like the Pods of a normal Service.
Since Envoy has no dedicated feature for Inference, Istio processes Inference Traffic by combining Envoy’s general-purpose features, the External Processing (ext-proc) Filter and the Override Host Load Balancing Policy. The Gateway’s Envoy that receives a Client’s Inference request forwards the request information to the EPP as in the Select Endpoint flow of [Figure 1], and the EPP selects the optimal Model Server Pod based on the Metrics collected through the Get Metrics flow and returns it to Envoy. Envoy forwards the request to the Model Server Pod returned by the EPP.
1.1. Test Environment Setup
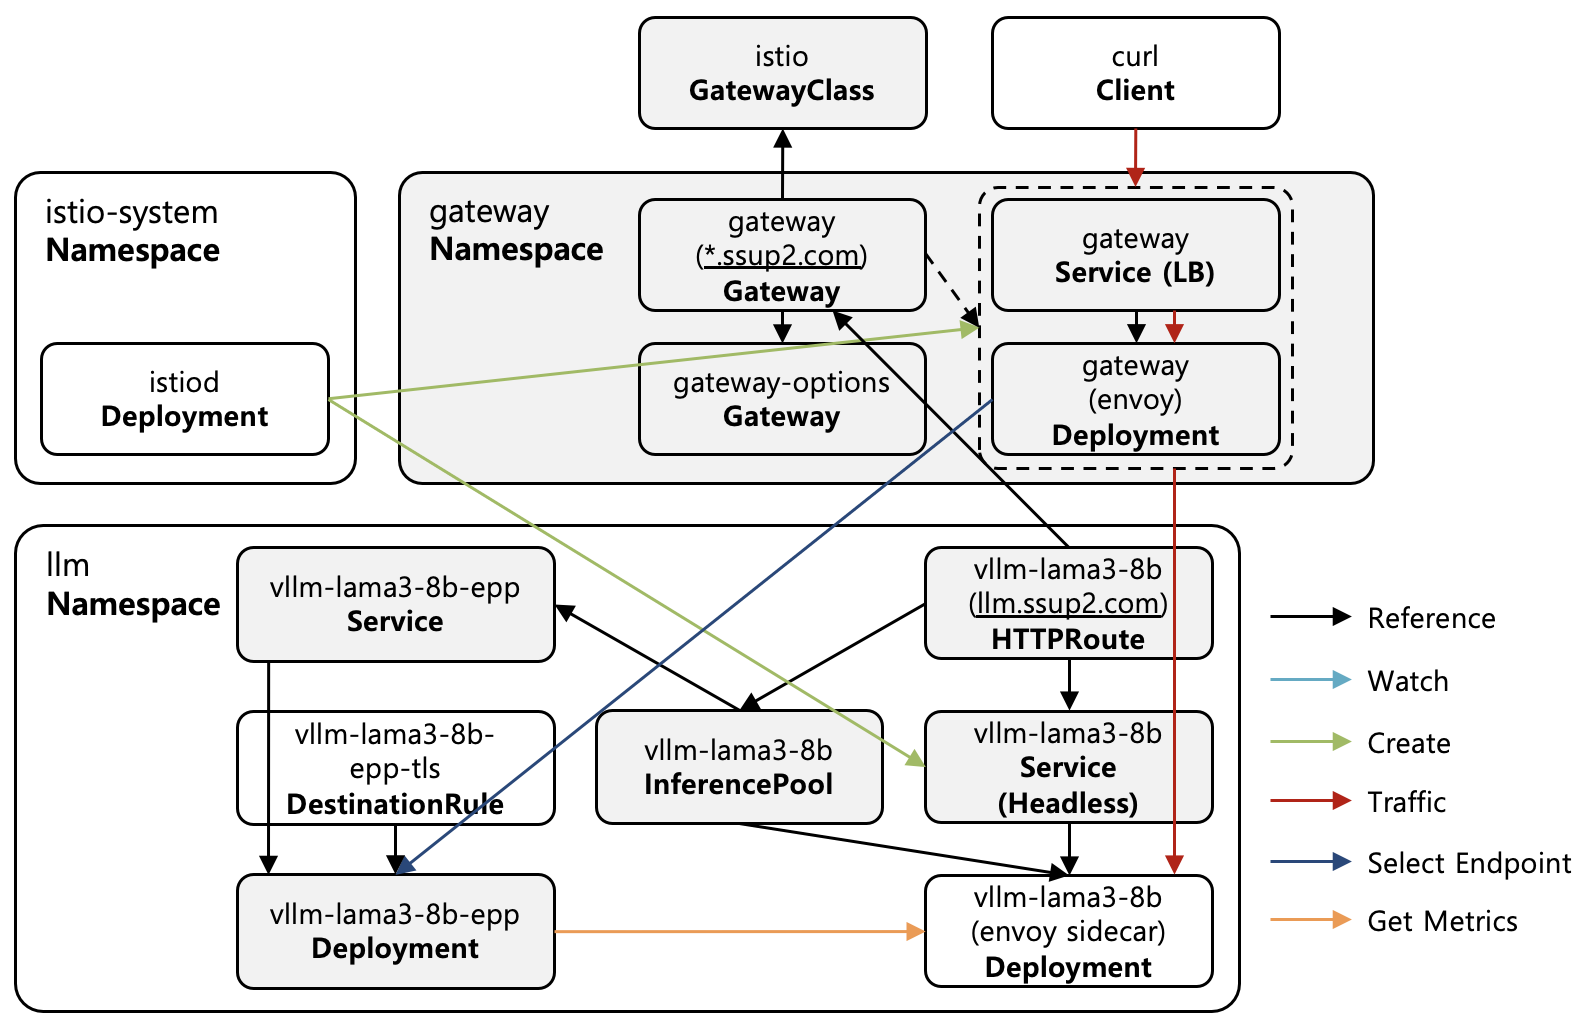
[Figure 2] Test Environment
# Create kind cluster
$ kind create cluster --name istio-gateway-api

# Install gateway api CRDs (v1.6.0 standard channel)
$ kubectl apply -f https://github.com/kubernetes-sigs/gateway-api/releases/download/v1.6.0/standard-install.yaml

# Install gateway api inference extension CRDs (v1.6.2)
$ kubectl apply -f https://github.com/kubernetes-sigs/gateway-api-inference-extension/releases/download/v1.6.2/manifests.yaml

# Install istio with gateway api inference extension
$ istioctl install --set profile=minimal \
    --set values.pilot.env.SUPPORT_GATEWAY_API_INFERENCE_EXTENSION=true \
--set values.pilot.env.ENABLE_GATEWAY_API_INFERENCE_EXTENSION=true -ySince the Gateway API Inference Extension is not yet enabled as a default feature of Istio, it must be enabled through istiod’s environment variables as shown in [Shell 1]. After enabling it, an Inference Gateway can be composed with only the Gateway API Inference Extension’s InferencePool and the Gateway API’s Gateway and HTTPRoute Resources, without any separate Istio-specific configuration. The behavior verification in the rest of this post is performed by installing the Gateway API v1.6.0 CRDs, the Gateway API Inference Extension v1.6.2 CRDs, and Istio 1.31.0 on a kind Cluster as shown in [Shell 1].
| |
$ kubectl -n llm-namespace get pods -o wide
NAME                                   READY   STATUS    RESTARTS   AGE    IP
vllm-llama3-8b-56d558cb78-hnfzl        1/1     Running   0          21m    10.244.0.13
vllm-llama3-8b-56d558cb78-nw2p4        1/1     Running   0          21m    10.244.0.14
vllm-llama3-8b-56d558cb78-vw58t        1/1     Running   0          21m    10.244.0.15
vllm-llama3-8b-epp-5dc6dcfddc-bjcq7    1/1     Running   0          21m    10.244.0.16

$ kubectl -n llm-namespace get services
NAME                         TYPE        CLUSTER-IP     EXTERNAL-IP   PORT(S)     AGE
vllm-llama3-8b-epp           ClusterIP   10.96.249.74   <none>        9002/TCP    21m
vllm-llama3-8b-ip-22dc7de1 ClusterIP None <none> 54321/TCP 21mThe Model Server of the Test environment is composed of 3 Pods of the vLLM Simulator, which runs without a GPU, as shown in [File 1], and the Lightweight EPP based vllm-llama3-8b-epp Deployment and Service are created together. Since the EPP receives requests over TLS, a DestinationRule for the TLS connection between the Gateway and the EPP is also configured, and the RBAC configuration that allows the EPP to look up the InferencePool and Pods is omitted from [File 1].
After applying [File 1], the 3 Model Server Pods, the EPP Pod, and the EPP Service can be seen created as shown in [Shell 2]. The vllm-llama3-8b-ip-22dc7de1 Service in the Service list is the Shadow Service that istiod creates once the InferencePool of [File 2] is applied later.
| |
$ kubectl -n llm-namespace get inferencepool
NAME             AGE
vllm-llama3-8b   40m

$ kubectl -n llm-namespace get inferencepool vllm-llama3-8b -o jsonpath='{range .status.parents[0].conditions[*]}{.type}={.status} ({.reason}){"\n"}{end}'
Accepted=True (Accepted)
ResolvedRefs=True (ResolvedRefs)[File 2] shows the Gateway of the istio GatewayClass that receives Traffic, the vllm-llama3-8b InferencePool that groups the Model Server Pods, and the HTTPRoute that forwards Traffic of the llm.ssup2.com Hostname to the InferencePool. [Shell 3] shows the InferencePool and its status after applying [File 2]. The Accepted Condition of the status confirms that the InferencePool is properly connected to the Gateway through the HTTPRoute, and the ResolvedRefs Condition confirms that the EPP reference specified in endpointPickerRef has been properly resolved. The behavior verification in the rest of this post is performed on the Test environment in this state.
1.2. InferencePool Conversion
istiod handles an InferencePool by converting it into Istio’s existing Service Model. When an InferencePool is created, istiod creates a Shadow Service as a Headless Service for each InferencePool, named in the form [InferencePool Name]-ip-[Hash].[Namespace].svc.cluster.local. Since the Shadow Service’s selector and Target Port are set to the InferencePool’s selector and Target Port, the Model Server Pods that match the selector are registered as the Shadow Service’s Endpoints. Therefore, the creation and removal of Model Server Pods are reflected in Envoy through EDS (Endpoint Discovery Service), the same as Istio’s existing Service Discovery.
In Envoy, an EDS Type Cluster in the form outbound|54321||[Shadow Service Name] corresponding to the Shadow Service is created. The 54321 in the Cluster name is a fixed virtual Port used for the Shadow Service, and the Port to which Traffic is actually forwarded is the InferencePool’s Target Port set on the Cluster’s Endpoints. If an InferencePool is specified in the backendRefs of an HTTPRoute, the Cluster of that Route is set to the InferencePool’s Shadow Service Cluster. Because Istio converts the InferencePool into the existing Service Model rather than handling it as a separate concept, the mTLS and Telemetry features provided by Istio can also be applied to the InferencePool’s Model Servers in the same way.
$ istioctl proxy-config clusters gateway-istio-6cf9dd97dd-8lrn4 -n gateway-namespace | grep vllm
vllm-llama3-8b-epp.llm-namespace.svc.cluster.local             9002      -          outbound      EDS        vllm-llama3-8b-epp-tls.llm-namespace
vllm-llama3-8b-ip-22dc7de1.llm-namespace.svc.cluster.local     54321     -          outbound      EDS

$ istioctl proxy-config endpoints gateway-istio-6cf9dd97dd-8lrn4 -n gateway-namespace | grep vllm-llama3-8b-ip
10.244.0.13:8000        HEALTHY     OK     outbound|54321||vllm-llama3-8b-ip-22dc7de1.llm-namespace.svc.cluster.local
10.244.0.14:8000        HEALTHY     OK     outbound|54321||vllm-llama3-8b-ip-22dc7de1.llm-namespace.svc.cluster.local
10.244.0.15:8000        HEALTHY     OK     outbound|54321||vllm-llama3-8b-ip-22dc7de1.llm-namespace.svc.cluster.local
[Shell 4] shows the Clusters and Endpoints of the Gateway Envoy after the vllm-llama3-8b InferencePool is created. Although no separate Service was created for the Model Servers, the Service list in [Shell 2] shows that the Shadow Service named vllm-llama3-8b-ip-22dc7de1 created by istiod exists as a Headless Service. In Envoy, the Cluster corresponding to the Shadow Service has been created, and the Cluster’s Endpoints show the 3 Model Server Pod IPs selected by the InferencePool’s selector registered together with the Target Port, Port 8000.
1.3. Request Processing Flow
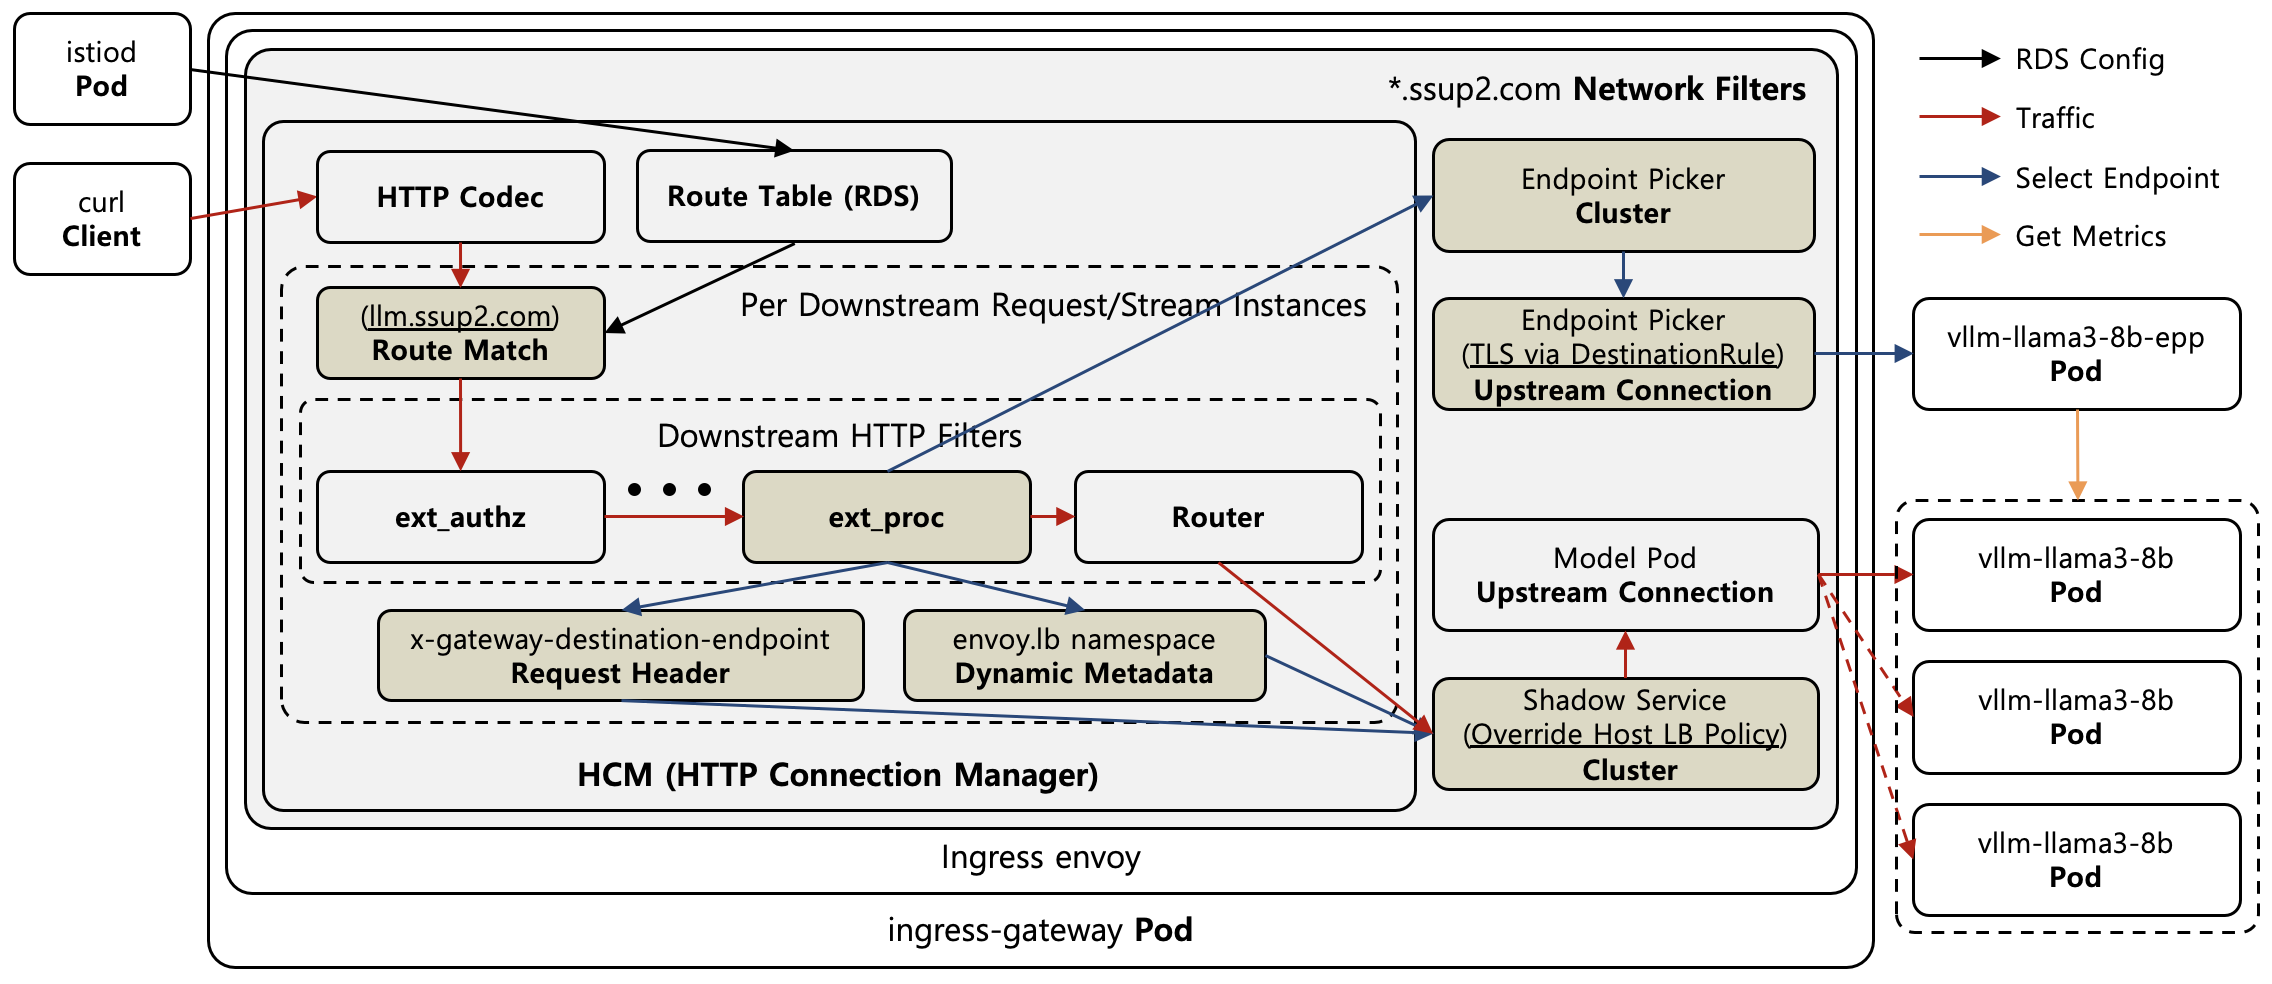
[Figure 3] Inference Request Processing Flow
[Figure 3] shows the Inference request processing flow of the Gateway Envoy. istiod delivers the Route Table containing the Route that references the InferencePool to Envoy via RDS, and the HTTP Connection Manager that receives a Client’s request Decodes the request with the HTTP Codec and then selects the Route corresponding to the llm.ssup2.com Hostname through Route Match.
Envoy’s ext-proc Filter is an HTTP Filter that forwards the Headers and Body of requests and responses to an external gRPC Server so the external Server can inspect and modify the Traffic, and in the Inference Extension, the EPP acts as the external gRPC Server that receives the ext-proc requests. As shown in [Figure 3], the ext-proc Filter is located in the middle of the Downstream HTTP Filter Chain, and the connection to the EPP is made through a separate Endpoint Picker Cluster with TLS applied by the DestinationRule of [File 1].
The Override Host Load Balancing Policy is a Load Balancing policy that, instead of selecting an Endpoint with a Load Balancing algorithm, reads the Endpoint address from a specific Header of the request or from the Envoy Metadata set on the request and forwards the Traffic to that Endpoint, and it is set on the Shadow Service Cluster as shown in [Figure 3]. Through these two features, Envoy forwards Inference requests to the Model Server Pod selected by the EPP.
$ istioctl proxy-config routes gateway-istio-6cf9dd97dd-8lrn4 -n gateway-namespace --name http.80 -o json
...
        "routes": [
            {
                "name": "llm-namespace.llm-route.0",
                ...
                "route": {
                    "cluster": "outbound|54321||vllm-llama3-8b-ip-22dc7de1.llm-namespace.svc.cluster.local",
                    ...
                },
                "typedPerFilterConfig": {
                    "envoy.filters.http.ext_proc": {
                        "@type": "type.googleapis.com/envoy.extensions.filters.http.ext_proc.v3.ExtProcPerRoute",
                        "overrides": {
                            "processingMode": {
                                "requestHeaderMode": "SEND",
                                "responseHeaderMode": "SEND",
                                "requestBodyMode": "FULL_DUPLEX_STREAMED",
                                "responseBodyMode": "FULL_DUPLEX_STREAMED",
                                ...
                            },
                            "grpcService": {
                                "envoyGrpc": {
                                    "clusterName": "outbound|9002||vllm-llama3-8b-epp.llm-namespace.svc.cluster.local"
                                }
                            },
                            "failureModeAllow": true
                        }
                    }
                }
            }
        ]
...
[Shell 5] shows the actual ext-proc Filter configuration set on the Route that references the InferencePool. The Route’s Cluster is set to the InferencePool’s Shadow Service Cluster, and the EPP’s Cluster is specified in the ext-proc Filter’s grpcService.
When the Gateway’s Envoy receives a request, Route Match selects the InferencePool’s Route according to the matches conditions of the HTTPRoute, and the ext-proc Filter set on the Route forwards the request’s Headers and Body to the EPP over gRPC. Since the ext-proc Filter is set only on Routes that reference an InferencePool, requests forwarded to normal Services on the same Gateway do not pass through the EPP. The Route configuration contains no part that designates a specific Pod; the Route is responsible only for forwarding the request to the EPP, and the behavior of forwarding the request to the Pod selected by the EPP is handled by the Load Balancing configuration of the Shadow Service Cluster.
$ curl -s -i -H "Host: llm.ssup2.com" http://127.0.0.1:8080/v1/completions \
    -d '{"model": "reviews-1", "prompt": "What do reviewers think about The Comedy of Errors?", "max_tokens": 100, "temperature": 0}'
HTTP/1.1 200 OK
...
server: istio-envoy
x-inference-pod: vllm-llama3-8b-56d558cb78-hnfzl
x-inference-port: 8000
...
{"id":"cmpl-02401d40-5ed9-5702-9895-6e8cf93783bb","created":1789907157,"model":"reviews-1","usage":{"prompt_tokens":10,"completion_tokens":36,"total_tokens":46},"object":"text_completion",...}
[Shell 6] shows the result of sending an Inference request to the Gateway through port-forward. The request is processed normally by the vLLM Simulator, and the x-inference-pod Header of the response identifies the Model Server Pod that processed the request.
# Port-forward to a model server pod
$ kubectl -n llm-namespace port-forward pod/vllm-llama3-8b-56d558cb78-hnfzl 8000:8000 &

$ curl -s http://127.0.0.1:8000/metrics
# HELP vllm:cache_config_info Information of the LLMEngine CacheConfig.
# TYPE vllm:cache_config_info gauge
vllm:cache_config_info{block_size="16",num_gpu_blocks="1024"} 1
# HELP vllm:kv_cache_usage_perc Prometheus metric for the fraction of KV-cache blocks currently in use (from 0 to 1).
# TYPE vllm:kv_cache_usage_perc gauge
vllm:kv_cache_usage_perc{model_name="meta-llama/Llama-3.1-8B-Instruct"} 0
# HELP vllm:lora_requests_info Running stats on lora requests.
# TYPE vllm:lora_requests_info gauge
vllm:lora_requests_info{max_lora="2",running_lora_adapters="",waiting_lora_adapters=""} 1.790053209e+09
# HELP vllm:num_requests_running Number of requests currently running on GPU.
# TYPE vllm:num_requests_running gauge
vllm:num_requests_running{model_name="meta-llama/Llama-3.1-8B-Instruct"} 0
# HELP vllm:num_requests_waiting Prometheus metric for the number of queued requests.
# TYPE vllm:num_requests_waiting gauge
vllm:num_requests_waiting{model_name="meta-llama/Llama-3.1-8B-Instruct"} 0
[Shell 7] shows the result of querying the /metrics Endpoint of a Model Server Pod. The EPP periodically collects the Metrics of each Model Server and selects the optimal Model Server Pod based on vllm:num_requests_waiting, which represents the number of requests waiting in the Queue, vllm:kv_cache_usage_perc, which represents the KV Cache utilization, and vllm:lora_requests_info, which represents the list of loaded LoRA Adapters. Since the specification of the Metrics that a Model Server must expose is standardized as the Model Server Protocol, Model Serving Platforms other than vLLM can also be used in the same way.
The EPP returns the address of the selected Pod to Envoy in the ext-proc response, and the address is set identically in two places as shown in [Figure 3]: a Header added to the request under the name x-gateway-destination-endpoint, defined as the standard by the EPP Protocol, and the dynamic_metadata field of the response. dynamic_metadata is a field defined in the ext-proc response Message so that the external Server can deliver values to be stored inside Envoy. Envoy’s ext-proc Filter takes the values of the envoy.lb Namespace from the response’s dynamic_metadata field and stores them as the Metadata of the request being processed. Unlike a Header, Metadata is not a value included and transmitted in the request message, but per-request state that Envoy maintains internally only while processing a single request.
Since the Override Host Load Balancing Policy is set on Envoy’s Cluster, Envoy forwards the request to the Pod specified in the Metadata instead of using a normal Load Balancing algorithm. If the Metadata does not exist, the Load Balancing algorithm configured as the Fallback is used.
$ istioctl proxy-config clusters gateway-istio-6cf9dd97dd-8lrn4 -n gateway-namespace \
    --fqdn "vllm-llama3-8b-ip-22dc7de1.llm-namespace.svc.cluster.local" -o json
...
        "loadBalancingPolicy": {
            "policies": [
                {
                    "typedExtensionConfig": {
                        "name": "envoy.load_balancing_policies.override_host",
                        "typedConfig": {
                            "@type": "type.googleapis.com/envoy.extensions.load_balancing_policies.override_host.v3.OverrideHost",
                            "overrideHostSources": [
                                {
                                    "metadata": {
                                        "key": "envoy.lb",
                                        "path": [
                                            {
                                                "key": "x-gateway-destination-endpoint"
                                            }
                                        ]
                                    }
                                }
                            ],
                            ...
                            "fallbackPolicy": {
                                "policies": [
                                    {
                                        "typedExtensionConfig": {
                                            "name": "envoy.load_balancing_policies.round_robin",
                                            ...
[Shell 8] shows the Override Host Load Balancing Policy set on the Shadow Service Cluster. The Endpoint address returned by the EPP is stored and referenced in Envoy’s envoy.lb Metadata under the x-gateway-destination-endpoint Key, and the Fallback Load Balancing algorithm can be seen set to Round Robin. Since the envoy.lb Namespace is set in the receiving_namespaces of metadata_options on the Listener’s ext-proc Filter, the Metadata that the EPP sets in the ext-proc response is received by Envoy and stored in a state that the Override Host Load Balancing Policy can reference.
The InferencePool’s failureMode is converted into the ext-proc Filter’s failure_mode_allow setting. When set to FailOpen, failure_mode_allow is set to true so that requests are still forwarded through Fallback Load Balancing even when the EPP fails, and when set to FailClose, requests fail when the EPP fails. Since the InferencePool of the Test environment is set to FailOpen, [Shell 5] shows that failureModeAllow has been converted to true.
2. References
- Istio Gateway API Inference Extension Support : https://istio.io/latest/blog/2025/inference-extension-support/
- Istio Gateway API Inference Extension Task : https://istio.io/latest/docs/tasks/traffic-management/ingress/gateway-api-inference-extension/
- Gateway API Inference Extension : https://gateway-api-inference-extension.sigs.k8s.io/
- Gateway API Inference Extension Deep Dive : https://www.cncf.io/blog/2025/04/21/deep-dive-into-the-gateway-api-inference-extension/
- Endpoint Picker Protocol : https://github.com/kubernetes-sigs/gateway-api-inference-extension/tree/main/docs/proposals/004-endpoint-picker-protocol
- Envoy Override Host Load Balancing Policy : https://github.com/istio/istio/issues/56230
- Istio InferencePool Conversion : https://github.com/istio/istio/issues/57638