Kubernetes Scheduler
1. Kubernetes Scheduler
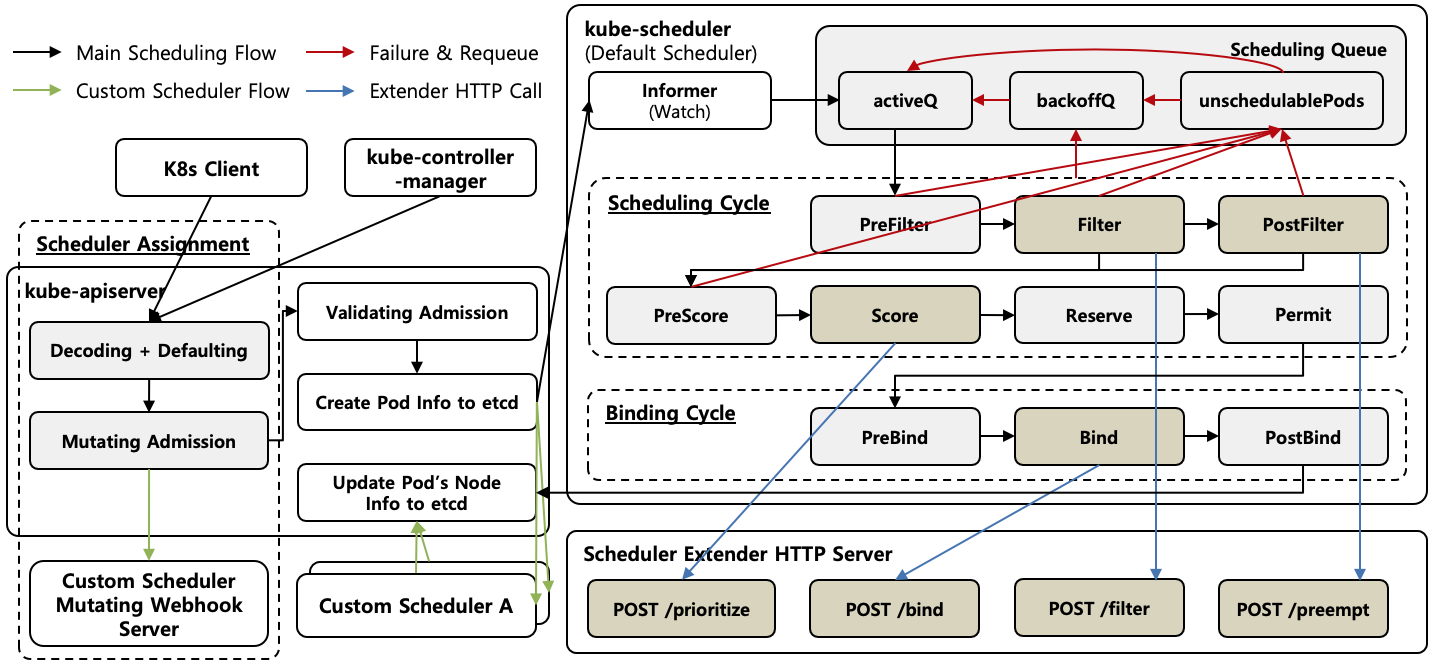
[Figure 1] Kubernetes Scheduler Architecture
Kubernetes Scheduler is the Control Plane Component that decides which Node a created Pod runs on. [Figure 1] shows the Architecture of Kubernetes Scheduler. The Scheduler responsible for a Pod is determined during the Defaulting and Mutating Admission processes of kube-apiserver when the Pod is created, and if no Scheduler is specified, the default Scheduler kube-scheduler is responsible for the Pod.
1.1. Scheduler Assignment
Each Scheduler running in a Kubernetes Cluster has a unique name, and the Scheduler responsible for a Pod is designated by specifying the Scheduler’s name in the Pod’s spec.schedulerName. Since each Scheduler takes only the Pods that match its own name and performs Scheduling, multiple Schedulers can be operated together in one Kubernetes Cluster based on names. Conversely, a Pod with a nonexistent Scheduler name specified remains in the Pending state because no Scheduler takes it.
| |
The name of kube-scheduler, the default Scheduler, is defined in the profiles of the KubeSchedulerConfiguration received through the --config parameter at startup, and [File 1] shows a Profile setting identical to the default settings. If profiles itself is omitted or the Profile’s schedulerName is omitted, kube-scheduler operates with a single Profile set to the name default-scheduler, and because of this default value, the name of the Default Scheduler becomes default-scheduler.
| |
[File 2] shows an example of a KubeSchedulerConfiguration defining two Profiles. The default-scheduler Profile operates as the Default Scheduler as it is because the Plugin configuration is not changed, and the no-scoring-scheduler Profile disables all Plugins of the PreScore and Score stages through the plugins setting, providing a Scheduler that decides a Node quickly without score calculation. By defining different Plugin configurations per Profile like this, a single kube-scheduler can operate multiple Schedulers with different Scheduling behaviors.
| |
[File 3] shows a Pod creation request with schedulerName omitted and the Pod stored in kube-apiserver. Since the omitted spec.schedulerName is automatically filled in the Defaulting stage of kube-apiserver, every stored Pod always has the name of its responsible Scheduler.
| |
Defaulting is the stage where kube-apiserver fills empty fields with the Defaulting functions registered per API version right after Decoding the request Body into an object, as shown in the Scheduler Assignment area of [Figure 1], and [Code 1] shows the Pod’s Defaulting function in abbreviated form. SetDefaults_PodSpec() sets default-scheduler, the value of the DefaultSchedulerName constant, to the empty schedulerName, together with the default values of other fields such as dnsPolicy and restartPolicy.
Since the Mutating Admission stage is performed after Defaulting, schedulerName is already filled with default-scheduler at the time a Mutating Admission Webhook receives the Pod. Therefore, to make a Custom Scheduler responsible for specific Pods, the filled schedulerName must be overwritten with the Custom Scheduler’s name in a Mutating Webhook, and since schedulerName is a field that cannot be changed after creation, such a change is possible only at creation time.
2. kube-scheduler
kube-scheduler is the default Scheduler of Kubernetes, and as shown in the kube-scheduler area of [Figure 1], it operates based on the Scheduling Framework. Extension Points are the points that the Scheduling Framework opens at defined stages from the Scheduling Queue to the Binding Cycle to call Plugins, and the basic features of kube-scheduler such as Resource checking and Affinity handling are also all implemented as built-in Plugins called at each Extension Point. The Scheduling behavior can also be extended by connecting self-implemented Plugins or external Webhooks to Extension Points. The operation of kube-scheduler is divided into the following three parts.
- Scheduling Queue : Pods without a decided Node are detected through the Informer’s Watch and stored in the Scheduling Queue, and Pods that failed Scheduling also return to the Scheduling Queue and wait for retry.
- Scheduling Cycle : Pops Pods from the Scheduling Queue one by one and decides a Node by passing through the Plugins of Extension Points.
- Binding Cycle : Binds the Pod to the decided Node by setting
spec.nodeName, and is performed asynchronously through a Goroutine.
2.1. Scheduling Queue
Scheduling Queue is the Queue where Pods without a decided Node wait for Scheduling. Through Extension Points such as PreEnqueue and QueueSort, the Scheduling Queue decides whether a Pod is ready to start Scheduling and the order in which Pods are popped, and the Scheduling Cycle pops and processes Pods one by one in this order. Pods that failed Scheduling return to the Scheduling Queue, and when a Cluster Event occurs afterward, QueueingHint determines whether to retry them.
2.1.1. Queue Structure
As also shown in [Figure 1], the Scheduling Queue is internally divided into three areas.
activeQ: A priority Queue storing Pods waiting for Scheduling.backoffQ: A Queue where Pods scheduled for retry wait during the Backoff time. It is an area to prevent repeatedly failing Pods from continuously occupying the serial Scheduling Cycle, and Pods move toactiveQafter the Backoff time that increases exponentially with the number of failures (from 1 second up to 10 seconds by default) passes.unschedulableEntities: An area storing Pods that would get the same result even if retried unless the Cluster’s state changes. UnlikebackoffQ, which Pods leave as time passes, Pods leave this area only when a Cluster Event that creates a possibility of Scheduling occurs. It was namedunschedulablePodsup to Kubernetes 1.36.
A Pod that fails Scheduling moves to a different area depending on the cause of the failure. When it failed because a Plugin rejected the Pod, kube-scheduler records the rejecting Plugin together with the Pod and stores the Pod in unschedulableEntities. On the other hand, a Pod that failed due to an error during Plugin execution or a temporary error such as a kube-apiserver request error needs retry regardless of Cluster changes, so it moves to backoffQ without going through unschedulableEntities.
A rejected Pod gets the same result no matter how many times it is retried unless the Cluster’s state changes, so it leaves unschedulableEntities only when a Cluster Event such as Node addition or Pod deletion occurs and creates a possibility of Scheduling. At the time of leaving, if the Backoff time remains, the Pod moves to activeQ via backoffQ, and if it has already passed, the Pod moves directly to activeQ, so backoffQ acts as a buffer section on the way back from unschedulableEntities to activeQ.
Also, even a rejected Pod does not always go through unschedulableEntities. Cluster Events that occurred while Scheduling was in progress may have been missed by the Pod, so kube-scheduler records them separately, and when the Pod fails and returns to the Queue, the recorded Events are examined and, if a possibility of Scheduling has arisen, the Pod moves to backoffQ without going through unschedulableEntities. In addition, there is a safeguard where Pods that have stayed in unschedulableEntities longer than a certain time (5 minutes by default) periodically move to backoffQ or activeQ even without an Event.
2.1.2. Extension Point
The Extension Points of the Scheduling Queue are as follows.
PreEnqueue: Checks whether the Pod is ready to start Scheduling before it entersactiveQ, and a Pod that does not pass cannot enteractiveQand waits inunschedulableEntities. A representative example is theSchedulingGatesPlugin, which blocks Scheduling until all of the Pod’sspec.schedulingGatesare removed.QueueSort: Decides the processing order of Pods stored inactiveQ. The default PluginPrioritySortsorts Pods so that Pods with a higher PriorityClass are processed first.
2.1.3. QueueingHint
| |
The relevance between a Pod stored in unschedulableEntities and a Cluster Event is judged through the QueueingHint provided by each Plugin, and [Code 2] shows the QueueingHint implementation of the NodeAffinity Plugin in abbreviated form. Each Plugin registers the kinds of Cluster Events that can affect its judgment through EventsToRegister(), and provides a QueueingHintFn that judges whether to retry for each Event. When a Cluster Event occurs, kube-scheduler calls only the QueueingHintFns of the rejecting Plugins recorded together with the Pod to receive a Queue or QueueSkip verdict.
For example, when there is a Pod stored in unschedulableEntities because no Node satisfies its Node Affinity condition and a new Node is added, the QueueingHintFn of the NodeAffinity Plugin examines whether the added Node’s Labels satisfy the Pod’s Node Affinity. If satisfied, the Pod moves to activeQ or backoffQ with a Queue verdict and Scheduling is retried, and if not, the Pod stays in unschedulableEntities with a QueueSkip verdict. Before QueueingHint was introduced, Pod movement was decided only by the kind of Event, so Scheduling retries with no possibility of success were repeated, but QueueingHint examines even the content of the Event, so unnecessary retries are eliminated.
In the case of Plugins that reject Pods in the Pending state to wait for the operation of external Controllers, such as the DRA Plugin, the rejection is not a wrong judgment of kube-scheduler, so on a Queue verdict the Pod moves directly to activeQ without going through backoffQ to reduce the waiting time.
2.2. Scheduling Cycle
Scheduling Cycle is the process of deciding the Node on which a Pod will run. The Scheduling Cycle pops Pods one by one from the Scheduling Queue and processes them serially, and a popped Pod passes through Extension Points such as Filter and Score in order to decide the Node on which it will run, and then moves on to the Binding Cycle. A Pod for which no Node could be decided returns to the Scheduling Queue.
2.2.1. Extension Point
The Extension Points of the Scheduling Cycle are as follows.
PreFilter: Preprocesses the Pod’s request information and checks preconditions before Filtering.Filter: Checks whether each Node can run the Pod and excludes impossible Nodes. Representative Plugins areNodeResourcesFitwhich checks the Node’s available Resources,NodeAffinitywhich checks Node Affinity, andTaintTolerationwhich checks Taints and Tolerations.PostFilter: Runs only when every Node has been rejected in Filtering. The default PluginDefaultPreemptionperforms Preemption, which evicts lower-priority Pods to secure placement space.PreScore: Receives the list of Nodes that passed Filtering before Scoring, and precomputes and stores information commonly needed for score calculation.Score: Calculates the score of each Node, and selects the Node with the highest score summed with weights applied per Plugin. Representative Plugins areNodeResourcesBalancedAllocationwhich evaluates the balance of Resource utilization, andImageLocalitywhich evaluates whether the Node has the Container Image.Reserve: Reflects the Resources the Pod will use on the selected Node in kube-scheduler’s internal Cache in advance.Permit: Approves, delays, or rejects the Pod’s Bind right before Bind. A delayed Pod waits for approval at the start of the Binding Cycle, as shown in Wait on Permit of [Figure 1], and it is used to implement Gang Scheduling, where multiple Pods must be placed together.
When a Plugin rejects the Pod at the PreFilter, Filter, Reserve, or Permit stage, the Pod moves to unschedulableEntities, and when every Node is rejected in Filtering, it moves after going through the Preemption attempt of the PostFilter stage. On the other hand, the PreScore and Score stages do not reject Pods and only calculate Node scores, so a failure at these stages is handled as an error and the Pod moves to backoffQ.
2.3. Binding Cycle
Binding Cycle is the process of Binding a Pod to the Node decided by the Scheduling Cycle. The Binding Cycle is performed asynchronously, separated from the Scheduling Cycle, and the Pod is Bound to the Node by passing through Extension Points such as PreBind, Bind, and PostBind in order. A Pod waiting for Permit approval that is rejected at the start of the Binding Cycle moves to unschedulableEntities, but since kube-scheduler regards only rejections up to Permit as unschedulable, a Pod that failed at the PreBind or Bind stage moves to backoffQ. In both cases, the Resources reflected at the Reserve stage of the Scheduling Cycle are rolled back.
2.3.1. Asynchronous Binding
The Binding Cycle is performed asynchronously because Bind is a slow operation that sends a request to kube-apiserver and waits for the response. kube-scheduler performs the Binding Cycle in a separate Goroutine, and starts the Scheduling of the next Pod immediately without waiting for the Bind to complete.
This asynchronous structure creates a risk of Resources being placed in duplicate. A Node’s remaining Resources are calculated by excluding the requests of the Pods whose spec.nodeName is set to that Node, but a Pod whose Bind has not finished does not have spec.nodeName yet and is missing from this calculation, so the next Pod being Scheduled in the meantime can take the same Resources again. kube-scheduler reflects the Resources the Pod will use in its internal Cache in advance at the Reserve stage of the Scheduling Cycle, and the Scheduling of the next Pod judges based on this Cache, so the decided placement is included in the calculation even before the Bind finishes and duplicate placement is prevented.
2.3.2. Extension Point
The Extension Points of the Binding Cycle are as follows.
PreBind: Performs preparation work needed before Bind. The representative Plugin isVolumeBinding, which Attaches Volumes to the Node.Bind: Sends a Binding request to kube-apiserver to set the Pod’sspec.nodeName. The set Node information is recorded in etcd through kube-apiserver, and the kubelet of that Node detects it and runs the Pod.PostBind: Performs cleanup work after the Bind completes.
2.4. Scheduler Extension
The Scheduling behavior of kube-scheduler can be extended by having self-implemented logic called at Extension Points, and depending on how it is called, it is divided into the Scheduling Framework Plugin method, which adds Plugins inside kube-scheduler, and the Scheduler Extender method, in which kube-scheduler calls an external HTTP Webhook server. The Scheduling Framework Plugin method can use all Extension Points and is fast because it operates through function calls, but kube-scheduler must be rebuilt. On the other hand, the Scheduler Extender method can be used only through configuration without rebuilding kube-scheduler, but the Extension Points it can intervene in are limited to some, and latency occurs due to HTTP round trips.
2.4.1. Scheduling Framework Plugin
| |
To operate as a Scheduling Framework Plugin, the Interfaces provided by the Scheduling Framework must be implemented, and [Code 3] shows these Interfaces in abbreviated form. Every Plugin implements the Plugin Interface, which returns its name, as the base, and must additionally implement the following Interfaces corresponding to the Extension Points where it operates.
| Extension Point | Stage | Interface | Methods to Implement |
|---|---|---|---|
PreEnqueue | Scheduling Queue | PreEnqueuePlugin | PreEnqueue() |
QueueSort | Scheduling Queue | QueueSortPlugin | Less() |
PreFilter | Scheduling Cycle | PreFilterPlugin | PreFilter(), PreFilterExtensions() |
Filter | Scheduling Cycle | FilterPlugin | Filter() |
PostFilter | Scheduling Cycle | PostFilterPlugin | PostFilter() |
PreScore | Scheduling Cycle | PreScorePlugin | PreScore() |
Score | Scheduling Cycle | ScorePlugin | Score(), ScoreExtensions() |
Reserve | Scheduling Cycle | ReservePlugin | Reserve(), Unreserve() |
Permit | Scheduling Cycle | PermitPlugin | Permit() |
PreBind | Binding Cycle | PreBindPlugin | PreBindPreFlight(), PreBind() |
Bind | Binding Cycle | BindPlugin | Bind() |
PostBind | Binding Cycle | PostBindPlugin | PostBind() |
Since Custom Plugins operate in the same way as built-in Plugins, they can implement every Extension Point in [Table 1], and they can also implement QueueingHint through EventsToRegister() of the EnqueueExtensions Interface.
| |
[Code 4] shows an implementation and registration example of a Custom Filter Plugin that excludes Nodes with the Maintenance Label set. Filter() is called per Node in the Filtering stage and returns a Success or Unschedulable Status to determine whether the Node passes. The implemented Plugin must be registered with app.WithPlugin(), and kube-scheduler must be rebuilt. After that, the Plugin can be used only after the Extension Point at which it is enabled is specified along with the Plugin name in the plugins setting of the KubeSchedulerConfiguration’s Profile. The scheduler-plugins Project, the official Kubernetes Plugin collection, uses this method.
2.4.2. Scheduler Extender
| |
Scheduler Extender is used by registering a Webhook server in the extenders of KubeSchedulerConfiguration as shown in [File 4]. The Extender provides four Verbs: filter which selects Nodes, prioritize which calculates Node scores, bind which performs Bind on behalf of kube-scheduler, and preempt which intervenes in selecting the eviction targets of Preemption, and kube-scheduler sends HTTP requests to the specified URL at each stage to reflect the Extender’s judgment. Filter, PostFilter, Score, and Bind, marked in [Figure 1] as Extension Points with Scheduler Extender, are the Extension Points corresponding to the four Verbs.
Since the intervention points are limited to these four, it cannot intervene in the remaining Extension Points such as Reserve or Permit. managedResources specifies the Resources the Extender is responsible for, and the Extender is called only for Pods requesting those Resources. If ignoredByScheduler is set to true, the Resource is excluded from kube-scheduler’s basic Resource checking, and the Extender takes full charge of judging whether allocation is possible.
The Scheduler Extender is also used together with separately deployed Custom Schedulers. hami-scheduler of HAMi, a GPU sharing Middleware, is a representative example, and it operates by deploying kube-scheduler and the Scheduler Extender as a single Pod and changing the spec.schedulerName of vGPU Pods to hami-scheduler through a Mutating Webhook.
3. References
- Kubernetes Scheduler : https://kubernetes.io/docs/concepts/scheduling-eviction/kube-scheduler/
- Kubernetes Scheduling Framework : https://kubernetes.io/docs/concepts/scheduling-eviction/scheduling-framework/
- Kubernetes Scheduler Configuration : https://kubernetes.io/docs/reference/scheduling/config/
- Pod Scheduling Readiness : https://kubernetes.io/docs/concepts/scheduling-eviction/pod-scheduling-readiness/
- Scheduler Extender Design : https://github.com/kubernetes/design-proposals-archive/blob/main/scheduling/scheduler_extender.md
- scheduler-plugins : https://github.com/kubernetes-sigs/scheduler-plugins